

[Sep-2026] NS0-094 PDF Dumps Are Helpful To produce Your Dreams Correct QA's
New NS0-094 exam Free Sample Questions to Practice
NEW QUESTION # 16
You just replaced the boot media on a NetApp AFF C80 system in a data center, and you need to reinstall NetApp ONTAP software on the boot media. However, a USB stick containing the ONTAP image is not available. Which two commands can you use to recover the boot media?
(Choose two.)
- A. boot_recovery -partner
- B. netboot
- C. boot_ontap maint
- D. boot_diags
Answer: A,B
Explanation:
The netboot command is used to boot the system over the network and load the ONTAP image when a USB device is unavailable. The boot_recovery -partner command restores the boot media configuration and retrieves required recovery information from the HA partner after the ONTAP image has been loaded.
NEW QUESTION # 17
You are replacing a boot device on a FAS8300 system that is running ONTAP 9.10P6 software.
You attach a USB memory stick to the external USB port on the storage controller but cannot access the memory stick. What step needs to be performed to access the boot device?
- A. Add the boot device before the BIOS is loaded.
- B. Set the port to "enabled" with setenv.
- C. You need to use ONTAP 9.11 or later software.
- D. The external USB port is not activated on NetApp systems.
Answer: B
Explanation:
When replacing a boot device on a FAS8300 system and using a USB memory stick for recovery or installation, the external USB port must be explicitly enabled. This is done through the setenv command in the boot environment.
Steps to Enable the External USB Port:
Reboot the system and interrupt the boot process to access the bootloader prompt.
At the bootloader prompt, use the following command:
arduino
Copy code
setenv usbport_enabled true
Save the configuration and proceed with the boot process.
NEW QUESTION # 18
During which two operations is the NVRAM replayed by the high-availability (HA) partner?
(Choose two.)
- A. when a node is halted
- B. during a negotiated takeover
- C. when the node loses power
- D. after triggering a sync core
Answer: B,C
NEW QUESTION # 19
In which two sections of AutoSupport can you find information to analyze the following panic?
(Choose two.)
Panic_Message: PCI Error NMI from
device(s):ErrSrcID(CorrSrc(0xf00),UCorrSrc(0x18)), RPT(0,3,0):Qlogic FC
16G adapter in slot 1 on Controller
- A. SSRAM-LOG
- B. ALL-COREDUMP.XML
- C. HA-RASTRACE.TGZ
- D. PCI-HIERARCHY.XML
Answer: A,C
Explanation:
To analyze the provided panic error, the two sections of AutoSupport that are essential for investigation are:
1. HA-RASTRACE.TGZ
What it is:
HA-RASTRACE.TGZ contains HA (High Availability) system trace logs. It records hardware diagnostics, error traces, and the HA system's response to hardware events. These logs are critical when analyzing hardware-related panics, including those caused by PCI errors.
Why it's relevant to the panic:
In the given panic message, the NMI (Non-Maskable Interrupt) error originates from a Qlogic FC
16G adapter. HA-RASTRACE.TGZ will provide detailed diagnostics, including the error reporting from the HA interconnect and other hardware diagnostics. Specifically, it may include information about how the system detected the PCI fault and any actions taken to protect the system state.
How to analyze:
Extract the HA-RASTRACE.TGZ file from the AutoSupport bundle. Review hardware-related trace messages for entries associated with the PCI bus or the Qlogic FC adapter.
Look for specific error codes or keywords like PCI Error, NMI, or Qlogic.
2. SSRAM-LOG
What it is:
SSRAM-LOG records low-level hardware error details, including PCI device register states and uncorrectable memory errors. It is particularly useful for analyzing errors originating in peripheral hardware like network or storage adapters connected via PCI.
Why it's relevant to the panic:
The panic message explicitly references a PCI Error NMI caused by a Qlogic FC adapter.
SSRAM-LOG captures detailed state information for PCI devices, which can help identify whether the fault originated in the adapter hardware, the PCI bus, or another related component.
How to analyze:
Extract the SSRAM-LOG from the AutoSupport bundle.
Search for PCI-related errors, including the specific error source IDs (e.g., ErrSrcID(CorrSrc(0xf00),UCorrSrc(0x18))).
Review the log entries to confirm the root cause of the NMI.
NEW QUESTION # 20
After replacing a failed controller, the engineer notices mismatched firmware versions between HA partners. What is the BEST action?
- A. Disable storage failover permanently
- B. Synchronize firmware to supported compatible versions
- C. Downgrade all disk firmware immediately
- D. Ignore the mismatch permanently
Answer: B
Explanation:
Firmware consistency across HA partners ensures stable failover behavior and hardware compatibility. Supported compatible versions should be synchronized according to NetApp procedures. Permanent failover disablement is unnecessary. Disk firmware downgrades are unrelated unless specifically identified in interoperability guidance.
NEW QUESTION # 21
During a new SVM deployment, all of the FC LIFs are showing an admin/oper status of up/down.
The LIF extended status is Waiting for Link. What is causing this status?
- A. The FC cables are bad.
- B. The sync-destination LIF is in switchover state.
- C. The switch fabric is not configured.
- D. NPIV is disabled on the switch.
Answer: D
Explanation:
FC LIFs showing Waiting for Link with an admin/oper state of up/down commonly indicates that NPIV is not enabled on the SAN switch ports. ONTAP FC target LIFs rely on NPIV support to establish the virtual FC connections.
NEW QUESTION # 22
Which NetApp tool provides a menu-driven interface for tests that search for and determine hardware problems within NetApp ONTAP based storage systems?
- A. Active IQ OneCollect
- B. System-level Diagnostics
- C. Panic Message Analyzer
- D. NetApp Digital Advisor
Answer: B
Explanation:
System-level Diagnostics provides a menu-driven interface that runs hardware diagnostic tests to identify and isolate hardware faults within ONTAP-based storage systems.
NEW QUESTION # 23
A new disk shelf was added to a NetApp ONTAP cluster nondisruptively. After using the disk show command, some of the disks in the shelf are not visible in the system. What is causing this issue?
- A. The disks in the new disk shelf are mixed sizes.
- B. The new disk shelf has a duplicate disk shelf ID.
- C. The disk count exceeds the maximum number of supported disks.
- D. The new disk shelf was cabled using a single-path configuration.
Answer: B
Explanation:
Duplicate shelf IDs cause ONTAP to be unable to uniquely identify all disks in the newly added shelf, resulting in some disks not appearing in the system after the nondisruptive shelf addition.
NEW QUESTION # 24
Which two steps are required to replace a drawer in a DS460c shelf? (Choose two.)
- A. Evacuate all drives in the drawer.
- B. Disconnect the cable chains from the chassis.
- C. Power off the shelf.
- D. Shut down both nodes.
Answer: A,B
Explanation:
To replace a drawer in a DS460c shelf, the following steps must be taken:
1. Disconnect the cable chains from the chassis
Why this is required:
Cable chains connect the drawer to the shelf and must be disconnected to safely remove the drawer.
2. Evacuate all drives in the drawer
Why this is required:
Drives must be removed to avoid damage during the drawer replacement process and to reduce the weight of the drawer for safe handling.
NEW QUESTION # 25
You notice the following system alert during a routine check of a four-node NetApp ONTAP cluster: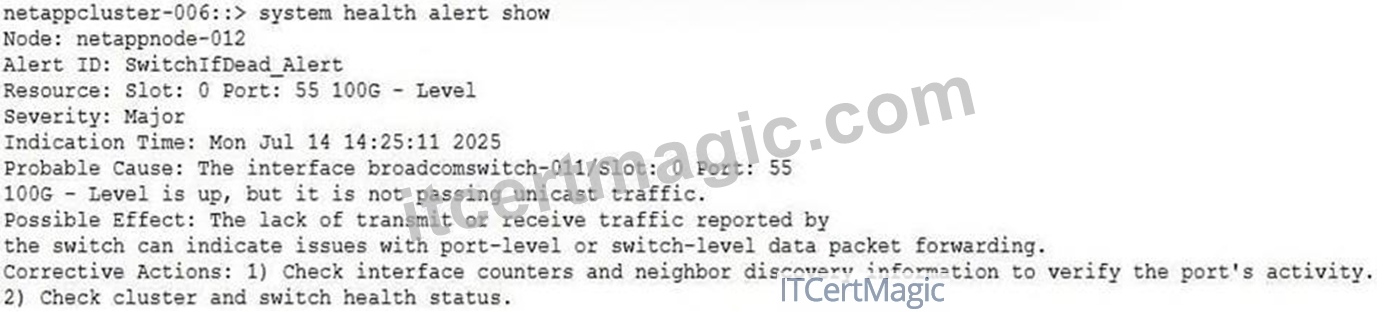
The customer confirms that the cables are connected correctly and interface LEDs on the switches are on.
What is the next step in troubleshooting this issue?
- A. Remove the cluster ports from the cluster IPspace and cluster broadcast domain, and delete the health alerts.
- B. Revert the ONTAP software upgrade to see if the alert disappears.
- C. Verify the configuration of the switchports with the output of RCF Configurator.
- D. Bounce the cluster interconnect ports on the ONTAP cluster nodes that are reporting this alert.
Answer: C
Explanation:
The alert indicates that the switch port is physically up but not passing unicast traffic, which commonly points to a switch port configuration mismatch. Verifying the switch port configuration against the RCF Configurator output is the appropriate next troubleshooting step.
NEW QUESTION # 26
You have an air-gapped NetApp ONTAP based system that has recently had a node panic, and the node is back online. To assist in troubleshooting, the NetApp Support team has asked you to submit the core file for analysis. Which two methods do you use to access the core files from the ONTAP controllers in this environment? (Choose two.)
- A. Use the system node autosupport invoke command.
- B. Collect files from the SPI of the affected nodes.
- C. Use the system node coredump upload command.
- D. Use the system node coredump external-device command.
Answer: B,D
Explanation:
The system node coredump external-device command is used in air-gapped environments to copy core files to an external storage device for transfer and analysis. Core files can also be accessed and collected through the Service Processor Infrastructure (SPI) of the affected nodes.
NEW QUESTION # 27
EMS reports "HA GROUP ERROR: DISK/SHELF COUNT MISMATCH." The ADP configured disks are distributed separately to two nodes.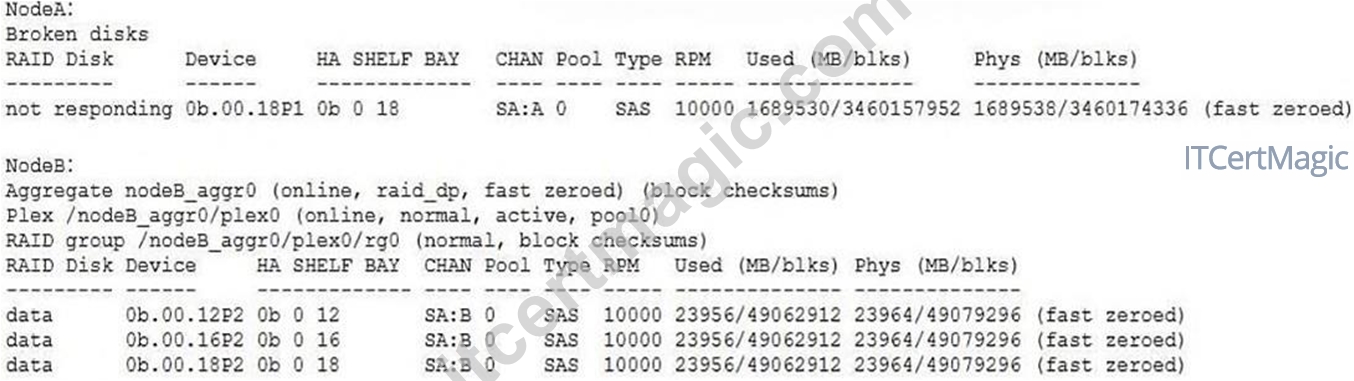
What is the cause of this issue?
- A. The disk in bay 18 is broken.
- B. The cabling to the NetApp NS224 shelf is incorrect.
- C. There is a disk firmware mismatch between the two nodes.
- D. The failed disk information is not synchronized between both nodes.
Answer: D
Explanation:
The output shows ADP partitions from the same physical disk being reported differently by the two nodes. This indicates that failed disk state information is not synchronized between the HA partners, causing the disk/shelf count mismatch alert.
NEW QUESTION # 28
You have upgraded your cluster from ONTAP 9.5 software to ONTAP 9.7 software. After two days, you notice that the upgrade is causing issues. You decide to revert to ONTAP 9.5 software.
Which two actions do you need to complete before you revert? (Choose two.)
- A. Revert from ONTAP 9.7 software to ONTAP 9.6 software and then to ONTAP 9.5 software.
- B. Delete all Snapshot copies from the past two days.
- C. Wipe your config and restore from backup.
- D. Reinstall your boot media and install ONTAP 9.5 software.
Answer: C,D
Explanation:
Reverting to a previous ONTAP version requires careful preparation because ONTAP upgrades often introduce irreversible changes. To successfully revert, the following actions are needed:
C). Reinstall your boot media and install ONTAP 9.5 software
You need to reinstall the older version of ONTAP (9.5) on the boot media because the current version (9.7) has been installed as part of the upgrade. The reinstallation ensures that the system boots with ONTAP 9.5.
Steps:
Boot the node into maintenance mode.
Perform the reinstallation using the appropriate ONTAP 9.5 image.
D). Wipe your config and restore from backup
A revert requires wiping the configuration because ONTAP upgrades may have made changes to the cluster configuration or WAFL metadata. Restoring the configuration from a backup ensures consistency with the older ONTAP version.
Steps:
Back up the current cluster configuration before proceeding.
Use the restored backup after the revert is complete to reconfigure the system.
NEW QUESTION # 29
What should be the first step taken after detecting a NetApp WAFL inconsistency?
- A. Run wafliron.
- B. Stabilize the system.
- C. Run a dump to null.
- D. Force offline the affected aggregate.
Answer: B
Explanation:
When a WAFL inconsistency is detected, the first step is to stabilize the system before attempting any repairs or recovery.
Steps to Handle WAFL Inconsistency:
Stabilize the System:
Ensure that the system is not experiencing ongoing hardware or software issues.
Avoid making changes to the affected aggregate or volume until the system is stable.
Assess the Impact:
Determine which aggregates or volumes are affected and the severity of the inconsistency.
NEW QUESTION # 30
What are two options to remove Failure Byte on disks that are marked as failed? (Choose two.)
- A. Reseat the disk.
- B. Unfail the disk
- C. Update the disk firmware.
- D. Power cycle the disk shelf.
Answer: A,B
Explanation:
If a disk is marked as failed, the Failure Byte on the disk indicates that the disk has been flagged for failure. This can be cleared using the following methods:
1. Reseat the Disk
What it does:
Physically remove the disk from the shelf and reseat it. This action can trigger the system to re- evaluate the disk's status and clear the Failure Byte if the failure was transient or due to connection issues.
2. Unfail the Disk
What it does:
Using the disk unfail command in maintenance mode clears the Failure Byte and returns the disk to service.
NEW QUESTION # 31
In preparation for an upgrade to ONTAP 9.6P8 software, you have uploaded the ONTAP image
96P8_q_nodar_image.tgz onto your local web server with address 192.168.10.10. Which is correct command syntax to download this image to the cluster image repository?
- A. ClusterA::> cluster image package get -url
http://192.168.10.10/96P8_q_nodar_image.tgz - B. ClusterA::> storage firmware download -node local -package-url
http://192.168.10.10/96P8_q_nodar_image.tgz - C. SP ClusterA?>; cluster image package get -url
http://192.168.10.10/96P8_q_nodar_image.tgz - D. ClusterA::> cluster image package get -url
http://netapp.com/ontap9/downloads/96P8_q_nodar_image.tgz
Answer: A
Explanation:
Command Syntax for Downloading ONTAP Image:
The cluster image package get command is used to download the ONTAP image from a specified URL to the cluster's image repository.
The syntax requires the -url parameter followed by the full URL of the image file.
Why Option C Is Correct:
This command syntax directly downloads the image from the local web server at
http://192.168.10.10/ to the ONTAP cluster repository.
Other options either refer to incorrect commands or unsupported URLs.
NEW QUESTION # 32
You are troubleshooting an L2 connectivity problem, and you want to analyze network traffic.
Which command do you use to capture network packets?
- A. traceroute
- B. netstat
- C. ping
- D. tcpdump
Answer: D
Explanation:
tcpdump is used to capture and analyze network packets for troubleshooting Layer 2 and network communication problems.
NEW QUESTION # 33
A 4-node NetApp ONTAP cluster sent an AutoSupport message for a single power supply failure in the cluster. The alert shows a failure for both node-1 and node-4. Why are two different nodes affected by the failure?
- A. There is a failure in cluster interconnect switch-1.
- B. There is a failover of node-2 to node-1.
- C. Both node-1 and node-4 are in the same chassis.
- D. There is a failover of node-3 to node-4.
Answer: C
Explanation:
A single power supply is shared by the controllers installed in the same chassis. Therefore, one failed power supply can generate alerts for both nodes that reside in that chassis.
NEW QUESTION # 34
During a health check you observe that NetApp ONTAP software is reporting CRC errors on a network port from a node in the cluster. Which component do you reseat?
- A. SFP
- B. cluster switch
- C. adapter
- D. data switch
Answer: A
Explanation:
CRC errors on a network port are commonly caused by a faulty or improperly seated SFP or cable connection. Reseating the SFP is the first corrective action to address physical layer transmission errors.
NEW QUESTION # 35
A customer wants to replace their NetApp AFF A800 HA pair with a new NetApp AFF A70 system without interruption. Which is used after joining the A70 to the existing cluster?
- A. Volume move
- B. SnapMirror synchronous
- C. Aggregate relocation
- D. SnapMirror SVM replication
Answer: A
Explanation:
After the new AFF A70 joins the existing cluster, the volume move operation is used to nondisruptively migrate volumes from the AFF A800 HA pair to the new system while client access remains online.
NEW QUESTION # 36
You are performing a head swap to upgrade your NetApp ONTAP controllers. After completing the first controller upgrade, the new controller does not show any cluster ports, and the new controller cannot communicate with the rest of the cluster. You verified that the new controller is cabled correctly, and swapped the cables, yet the ports still do not show. Which action resolves the issue and enables the new controller to communicate with the cluster?
- A. Create new network ports, then create new cluster interfaces and add them to the cluster broadcast domain.
- B. Modify the cluster interfaces, and add the interfaces to the cluster broadcast domain.
- C. Create new cluster interfaces, and add the interfaces to the cluster broadcast domain.
- D. Modify the network ports, and modify the cluster interfaces to the cluster broadcast domain.
Answer: B
Explanation:
During a head swap, the new controller may have different physical cluster port names. The existing cluster LIFs must be modified to use the new ports, and those ports must belong to the cluster broadcast domain so the controller can communicate with the cluster.
NEW QUESTION # 37
During power on, a memory error is diagnosed, and the system fails to boot NetApp ONTAP software. As AutoSupport is not enabled, a part must be requested from NetApp Support. What action do you take to address this issue?
- A. Boot into diagnostics mode.
- B. Log into NetApp ONTAP System Manager to gather details.
- C. Open a case through https://support.netapp.com.
- D. Use NetApp Active IQ to drill down on the issue.
Answer: A
Explanation:
Booting into diagnostics mode allows the engineer to run hardware memory diagnostics and collect the detailed failure information required to identify the faulty DIMM and request the correct replacement part from NetApp Support.
NEW QUESTION # 38
After you configure a new interface group with ports e2a and e2b, the ports are showing as down in the interface group.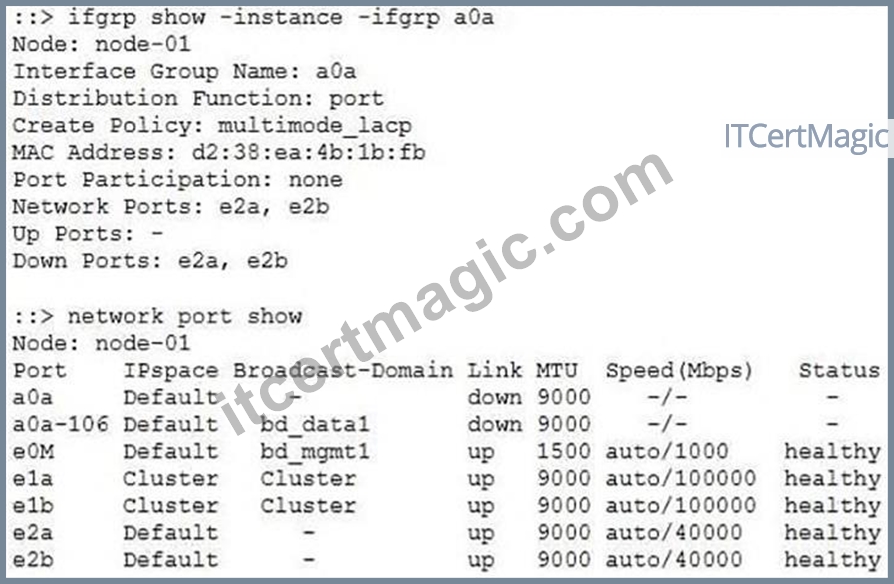
Which two actions correct the issue? (Choose two.)
- A. Modify ports e2a and e2b to -autonegotiate-admin false -speed-admin 40000.
- B. Verify the switch side LACP configuration.
- C. Add the ports e2a and e2b to broadcast domain bd_data1.
- D. Ensure that the switch ports are correctly cabled.
Answer: B,D
Explanation:
The interface group is configured for multimode LACP, but the member ports show no participation and remain down in the ifgrp. This indicates that the physical switch-side connectivity or LACP configuration is not properly established, so the cabling and switch LACP configuration must be verified.
NEW QUESTION # 39
A NetApp node fails to boot and displays repeated boot-loop behavior after hardware maintenance. Which troubleshooting step should be performed FIRST?
- A. Verify recently installed FRUs and cable seating
- B. Destroy the root aggregate
- C. Reset all cluster licenses
- D. Replace every disk in the shelf
Answer: A
Explanation:
After maintenance, improperly seated FRUs or disconnected cables are common causes of boot loops. Engineers should first validate hardware installation integrity before performing destructive actions. Replacing all disks or resetting licenses introduces unnecessary disruption and does not address likely root causes.
NEW QUESTION # 40
A customer opened a support ticket with this error message:
Mon Oct 17 19:16:56 +0800 [Nodename: dsa_disc:
callhome.dsk.redun.fault:error]: Call home for DISK REDUNDANCY FAILED
What is the cause of the EMS message in the event log?
- A. The system has no spare disks available.
- B. The system is updating the disk firmware.
- C. One node has one path to a disk shelf.
- D. The configured RAID group has a broken disk.
Answer: C
Explanation:
The DISK REDUNDANCY FAILED EMS message indicates that redundant disk access paths are no longer available. This commonly occurs when a node has only a single path remaining to a disk shelf instead of the expected multipath connectivity.
NEW QUESTION # 41
......
Cover NS0-094 Exam Questions Make Sure You 100% Pass: https://passitsure.itcertmagic.com/NetworkAppliance/real-NS0-094-exam-prep-dumps.html